
Many people who are blind and visually impaired now use AI in their everyday lives to make visual information accessible to them. With a smartphone in hand, they can simply take a picture of their supplement bottle or outfit and get a detailed AI-generated description. But AI outputs are not always accurate. These models can produce confident sounding, but ultimately incorrect answers, like misreading “6mg” as “8mg” on an ingredient table, or describing an outfit as “business casual” when most people would disagree.
Research shows that AI models fail to provide a reliable confidence score of their answers. As lengthier AI-generated descriptions can mix true and false claims together, it becomes hard to detect the false claims without sight, especially when the description sounds coherent and helpful. These unnoticed errors pose immediate safety and social risks, and visually impaired people may miss opportunities to learn AI limitations over time.
Researchers from the University of California, Berkeley collaborated with the Notre Dame-IBM Tech Ethics Lab to develop a system that reveals the errors and biases in AI-generated image descriptions. The team included project PI Amy Pavel, Meng Chen, and Notre Dame collaborator Toby Li.
To create the system, the team took inspiration from everyday moments when comparing conflicting opinions can actually help to make a better decision. If three people tell you the same story, you feel more confident. If they contradict each other, you might slow down and look closer. Blind users of AI tools have also already adopted this “cross-checking” method today. They might rerun an AI model multiple times, try a different app, or ask a sighted friend to check key details.
Yet comparing multiple descriptions can be exhausting, especially when using a screen reader, an assistive technology that linearly reads out the information on the screen in audio. The friction can make many users give up and revert to simply hoping that the first answer they receive is correct.
To address this need, the research team built a novel system to give blind users a full understanding of the relevant visual information available, surfacing agreements and disagreements from multiple sources. The system first presents a summary of agreements, disagreements, and unique findings (outputs generated from only one source) from each answer to provide a high-level understanding of the reliability of AI-generated descriptions. If the user wants to examine the description in more detail, the system also provides a novel format called “variation-aware description” that aggregates the variation in each detail of information into a hierarchical format (e.g., “There is a laundry basket or a storage bin,” “The sofa is grey or green”). By utilizing this new system, users found it much easier to tell where an AI description was reliable and where it was uncertain, so they could decide what information to trust.
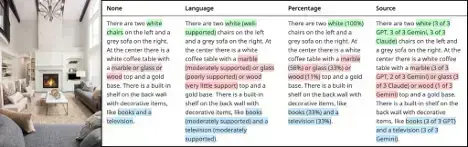
The team tested the efficacy of their technical pipeline and interface design with 15 blind users. Results showed that when people could see the variation across AI descriptions, they caught 4.9x more unreliable claims and calibrated their trust in AI systems from “pretty reliable” to “I should be cautious”. All participants in the study reported that they were excited about using the system in the future for a variety of purposes, from high-stakes scenarios such as assessing the path of an incoming tornado to obtaining subjective critiques for social media posts.
The team open-sourced the prototype system and shared their findings at ASSETS 2025, the premier forum for computing systems and accessibility. For a deeper dive into their findings, see their publication.